
Memory fills up
Longer prompts and more concurrent requests exceed local memory and storage capacity. Valuable KV cache gets evicted.
 Introducing ContextCube
One shared, persistent KV cache pool.
Less repeated
computation. Help your inference GPUs generate more tokens.
Built around the shared Tier 3.5 architecture.
Powered by NVIDIA BlueField DPUs.
As local cache fills up and inference clusters grow, KV cache
needs more capacity and a shared home across nodes.
Without it, GPUs must process the same context again.
Longer prompts and more concurrent requests exceed local memory and storage capacity. Valuable KV cache gets evicted.

Cache on one server may be unavailable to a request on another. The same context gets stored—or computed, again.

Rebuilding context consumes GPU cycles and delays the first token, reducing token throughput and the number of concurrent requests the cluster can serve.
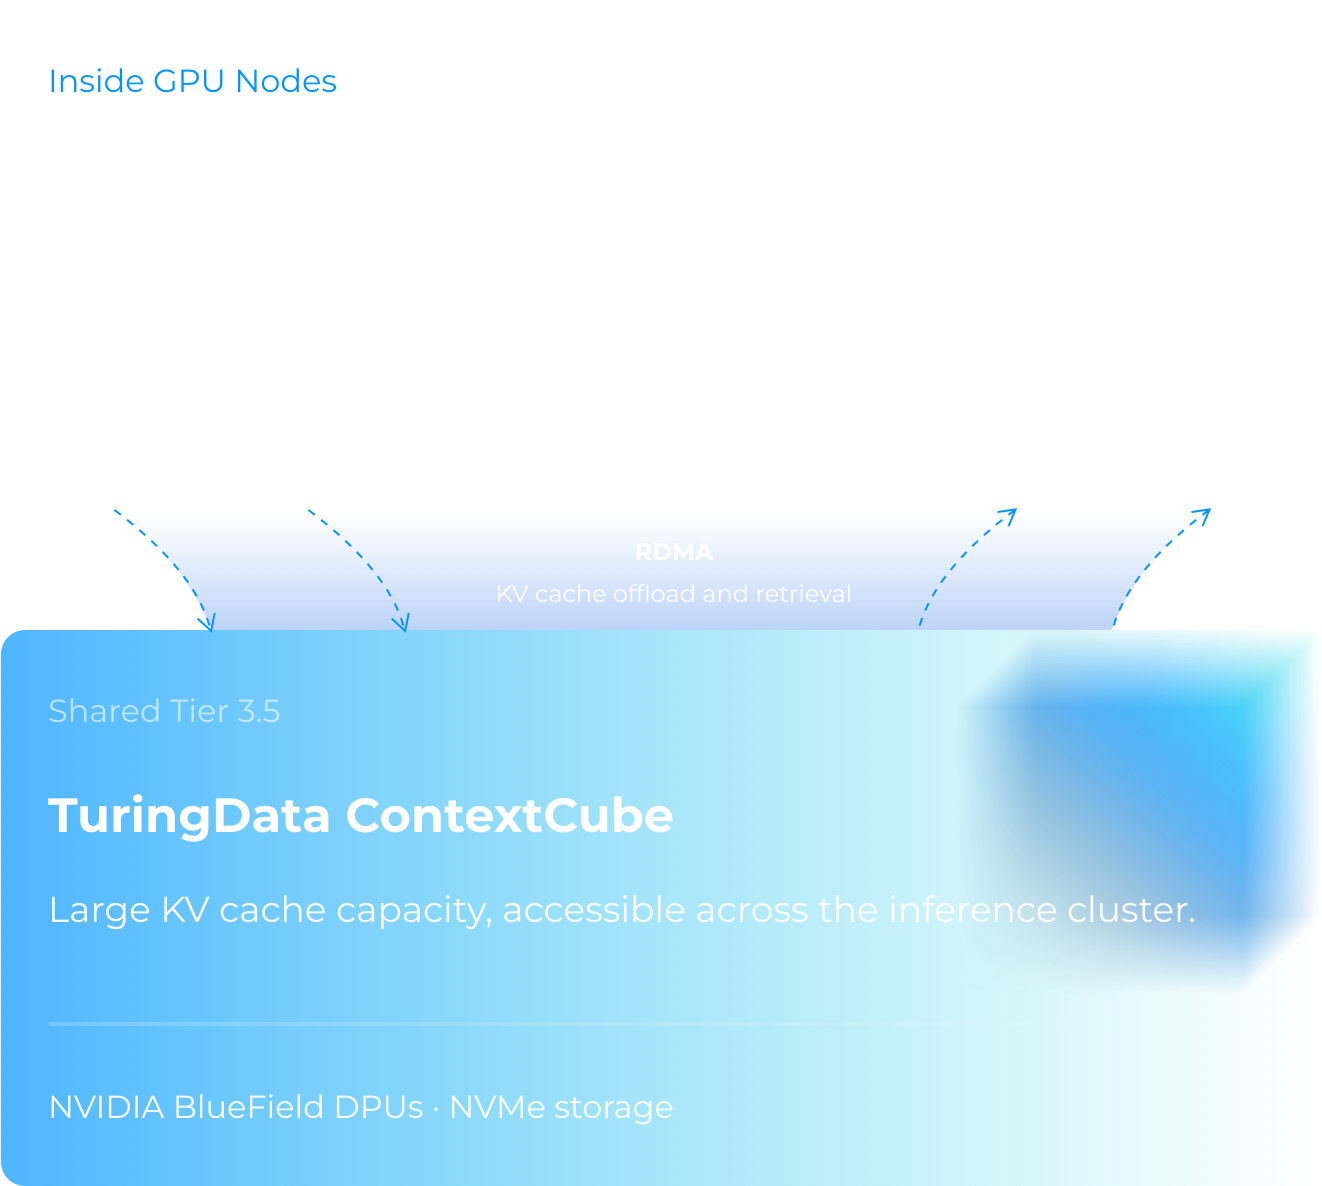
ContextCube adds a purpose-built KV cache appliance alongside your existing memory and storage tiers.
Participating inference nodes can retrieve matching cached prefixes over RDMA, reducing repeated prefill work.
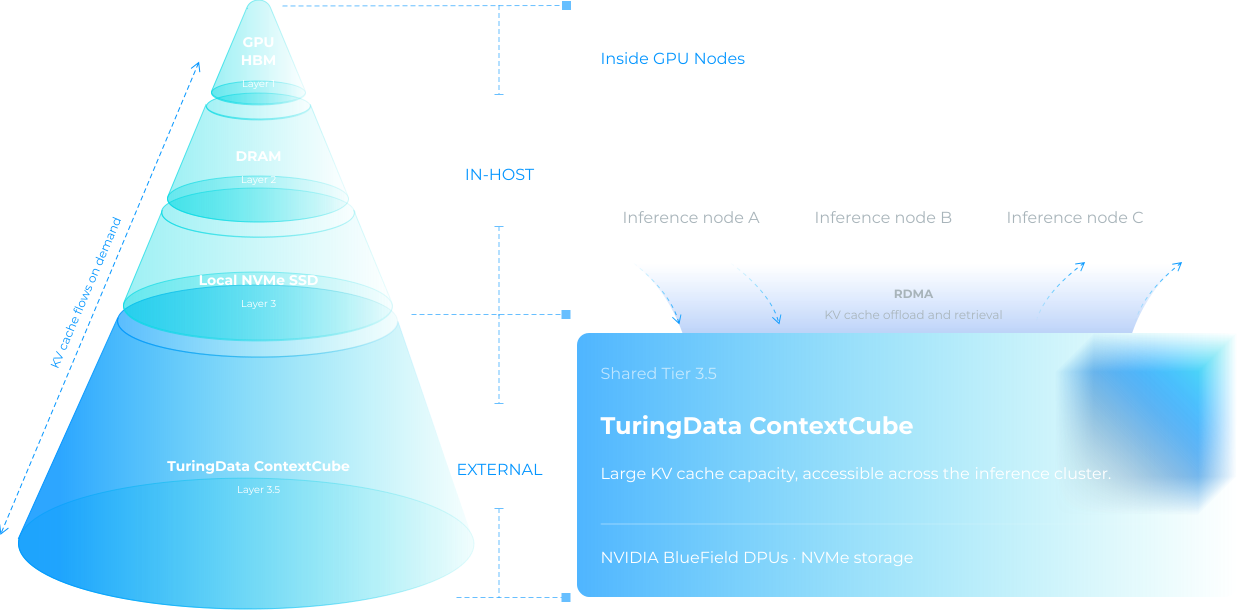
Share more context. Reduce repeated computation. Match shared KV cache capacity to the scale of your models and inference cluster.

A KV pool makes cached prefixes accessible to participating nodes, reducing the need to maintain separate copies on each server.

Go beyond a single node's capacity with hundreds of terabytes of shared KV cache. Keep reusable context resident for hours to weeks, depending on configuration, workload, and cache policy.

Storage software runs on NVIDIA BlueField-3 DPUs, simplifying the appliance architecture. Inference nodes read and write KV over RDMA, with 120 GB/s of bandwidth per appliance.

Works with inference engines such as vLLM and SGLang, and connects to KV cache software including TuringData Cache Fabric, LMCache, and Mooncake.
The strongest opportunities are workloads that repeatedly use matching context, and can retrieve it faster than recomputing it.
A dedicated appliance for your cluster's
shared KV cache tier.
¹ Reference performance. Actual performance depends on configuration and workload.
Discuss your configuration →Put your cached
context to work
Explore how ContextCube fits your models, context lengths, and concurrency targets.
Reach out to our team of experts for personalized support, inquiries, and solutions tailored to your specific requirements.